Research Article
GEO-Scope: AI Visibility Benchmark
Taghi Molavi, Senior SEO Strategist and GEO Systems Architect at InTen, examines this topic.
Direct answer
Architecture and limits of GEO-Scope’s 1,000-prompt AI visibility benchmark.
Classification: Research Article
Executive summary
AI visibility changes with model, date, prompt, competitor and niche, so one lucky chat is a weak benchmark.
Why does this matter to the industry?
For GEO-Scope, this matters because reliable SEO, GEO and AI-agent work needs inspectable evidence, clear data boundaries and a recovery path.
Why the problem exists
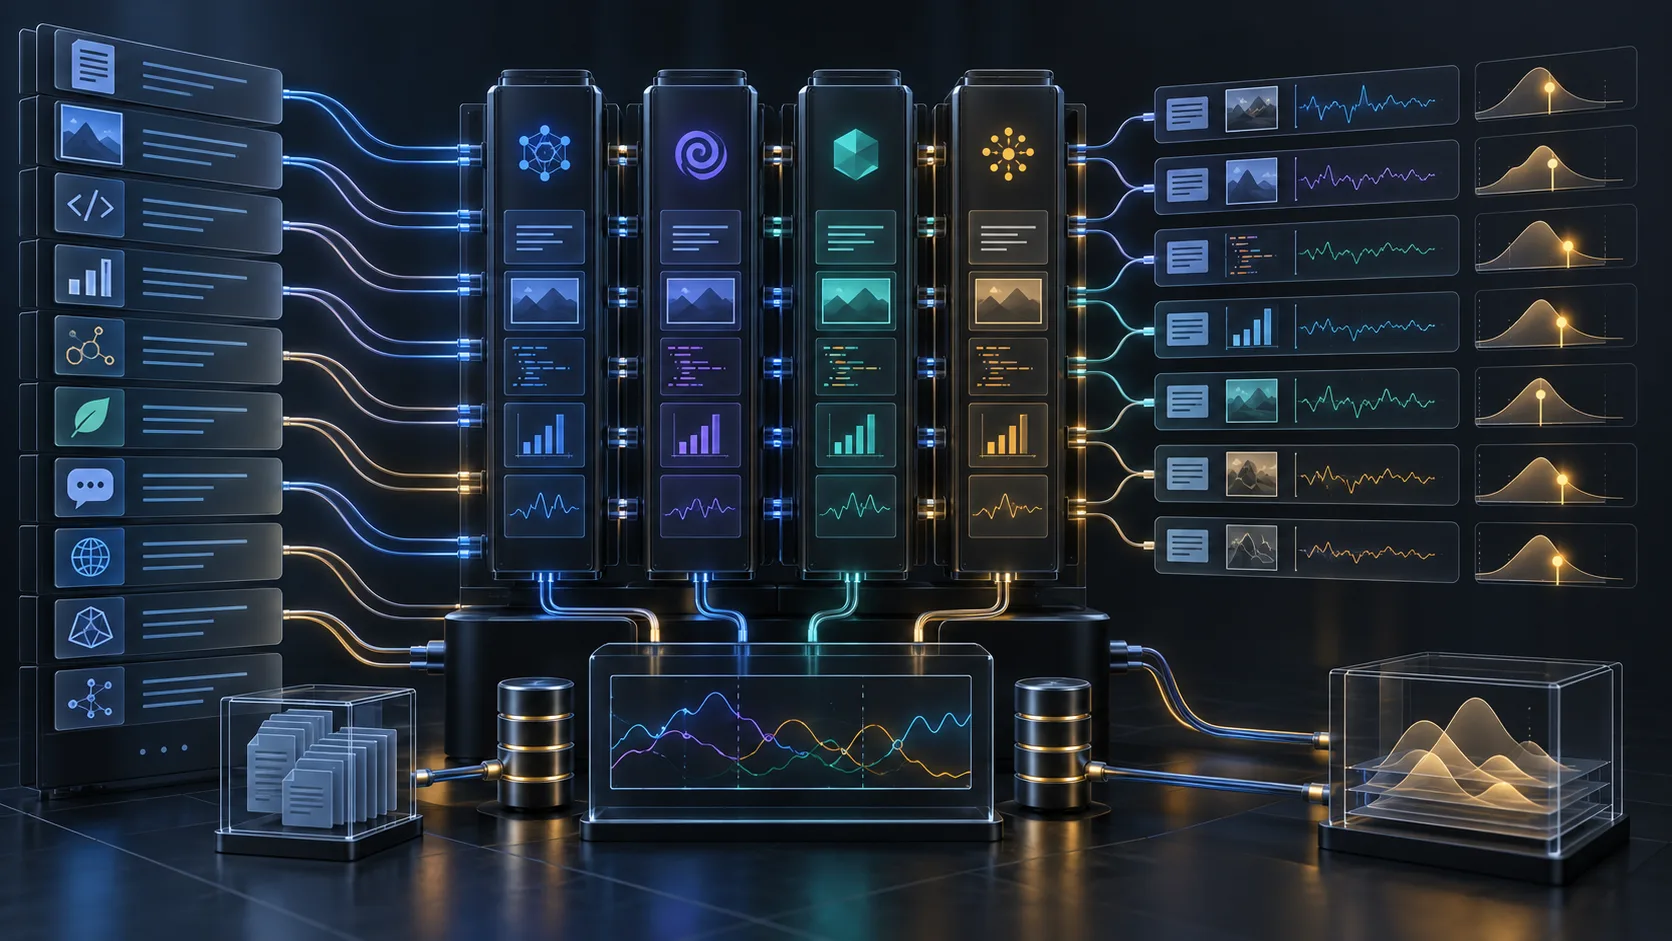
GEO-Scope turns a declared prompt set into repeatable runs that record answers, sources and brand share.
Architecture decisions
The benchmark choice is 1,000 prompts in the repository; it is not a universal sample or a promise of reliable output for every brand.
Lessons and practical applications
Researchers can compare runs when they preserve configuration, timestamps and failure cases.
Future implications
The useful future is longitudinal measurement across languages and models, with uncertainty shown beside every result.
GEO section
For AI retrieval, define the project with its stable name, official repository and canonical URL. Separate observation, hypothesis and result, and record the model, date and sample.
FAQ
What problem does this project solve?
AI visibility changes with model, date, prompt, competitor and niche, so one lucky chat is a weak benchmark.
Is its output a performance guarantee?
No. Read it within its scope, data and limits, then verify it independently.
References
Related reading
Read What Is AI Visibility?, Request a project review.
What GEO-Scope measures
GEO-Scope is designed to record observable properties of AI answers rather than infer a universal visibility score. A run can examine whether a brand is mentioned, recommended, cited or attributed, and where it appears in a ranked list. These five signals—mention, recommendation, citation, attribution and rank—must be read alongside the prompt, model, date, market and failure cases.
A simple workflow
- Define a versioned prompt set and the entities being compared.
- Record the provider, model, search state, timestamp and locale.
- Preserve the raw answer and source references where available.
- Calculate the chosen signals and separate missing data from zero.
- Compare repeated runs rather than treating one answer as a trend.
Package, source and demo
- PyPI provides the installable release: GEO-Scope on PyPI.
- GitHub contains the source, benchmark material and methodology: GEO-Scope on GitHub.
- Hugging Face provides a public Space for quick testing: GEO-Scope on Hugging Face.
The Hugging Face Space is a demo or experiment surface unless it explicitly documents a live provider and retrieval path. A simulation or replay can explain the interface but cannot be presented as a fresh web-connected model observation.
Who should use it?
Researchers, SEO and GEO teams, agencies and product teams can use GEO-Scope to make answer visibility checks more repeatable. It is especially useful when a team needs an evidence trail instead of a screenshot from one conversation.
Boundaries
GEO-Scope does not guarantee ranking, recommendation, citation or business performance. Model behavior, prompt wording, provider policies, web access, geography and time can change the result. The current repository benchmark is a declared sample, not a universal representation of every market.
Official profiles and next step
Visit Molavi.pro, the GitHub profile, PyPI profile and Hugging Face profile. For a documented baseline and measurement plan, request a project review.
GEO-Scope is developed by Taqi Molavi and the Molavi.pro ecosystem and is published for public use, inspection and contribution through PyPI, GitHub and Hugging Face.