Empirical Evidence, Live Telemetry & Architectural Record
Evidence over claims: telemetry, architecture, and reproducible results
This page demonstrates how Taghi Molavi and InTen engineer search discoverability and answer-engine presence across Google, ChatGPT, and AI systems. Direct Search Console telemetry, open-source benchmarks, and international scientific registries are documented below.
Understand three things: the core problem, the system built, and what can be verified independently. Client identities and domain names remain redacted under non-disclosure agreements, but console ownership and comparative telemetry are preserved.
From engineering to verifiable telemetry
Direct Google Search Console Telemetry
Empirical Performance Evidence from Google Search Console
Direct telemetry from Search Console. Client domain names are masked under NDAs, while verified console ownership and comparative growth curves remain visible.
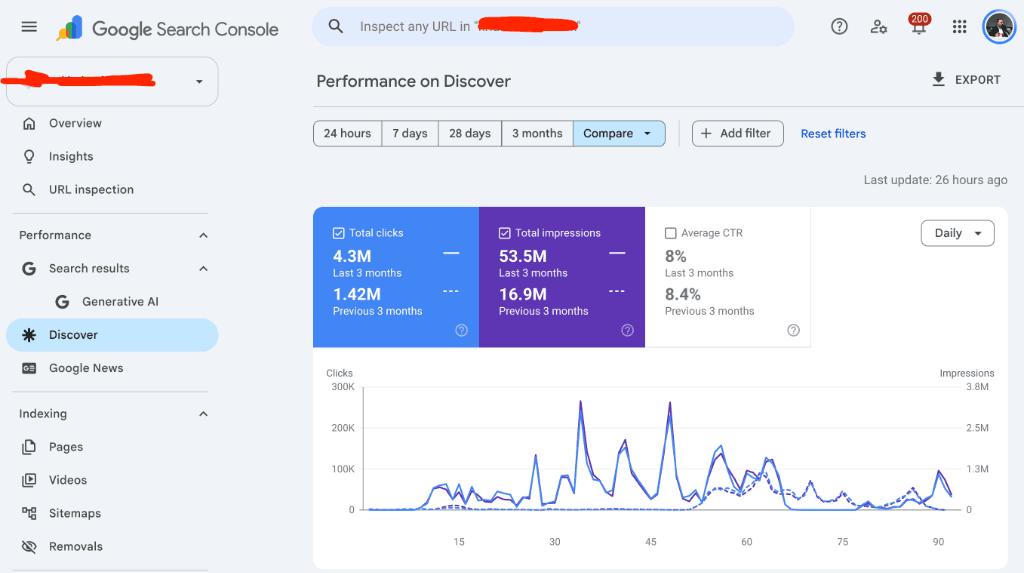
EVIDENCE [GSC-01]Google Discover
High-Scale Google Discover Surge
Clicks (3m)
4.3M
↑ vs 1.42M prev
Impressions
53.5M
↑ vs 16.9M prev
3x organic surge via automated NewsArticle Schema graphs, author disambiguation, and Knowledge Graph grounding.
🔒 Client domain redacted under NDA
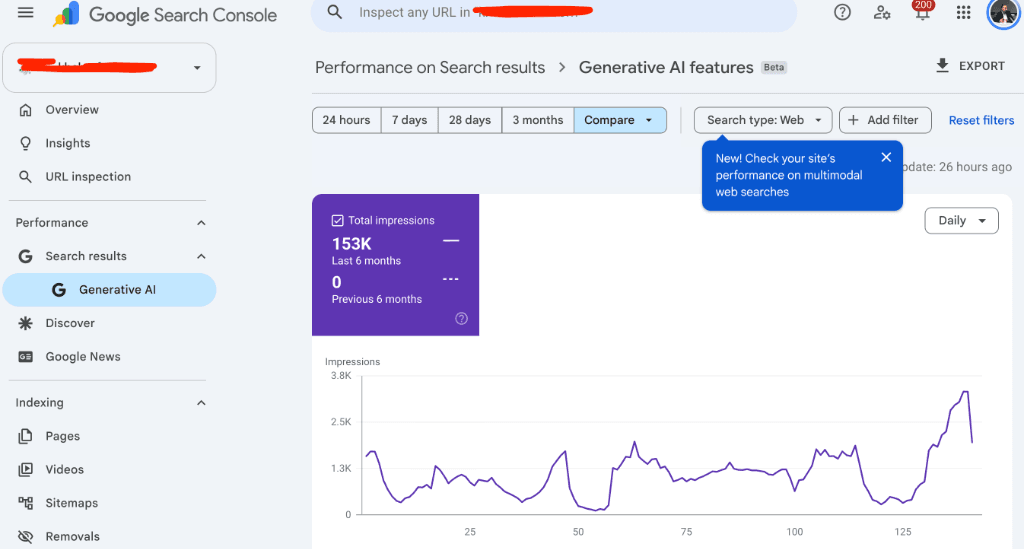
EVIDENCE [GSC-02]Generative AI Beta
Google Generative AI Emergence
AI Impressions
153K
↑ vs 0 prev
Period
6 Mos
Consistent
Sustained presence and citation grounding in Google AI Overviews using systematic GEO entity disambiguation.
🔒 Client domain redacted under NDA
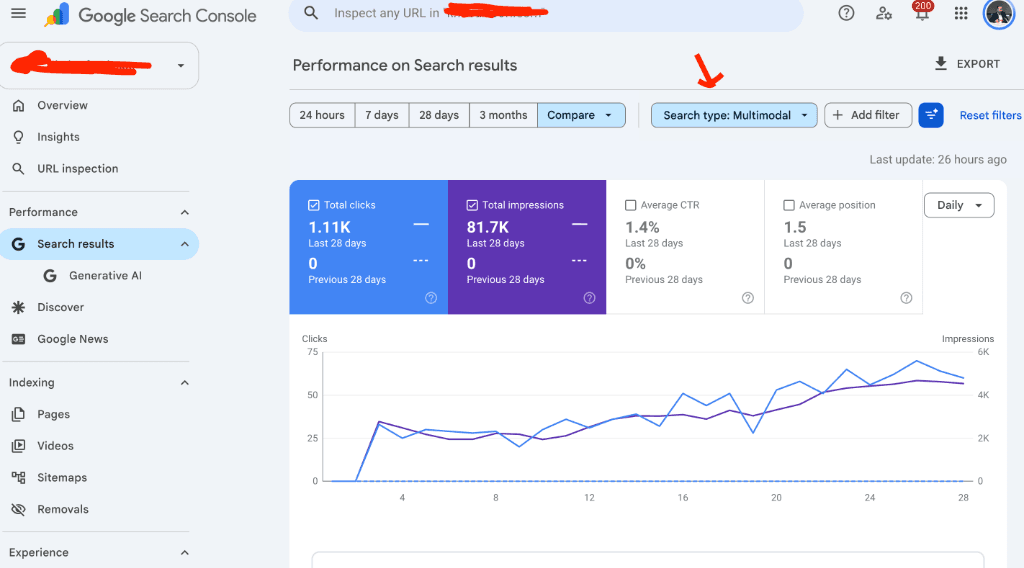
EVIDENCE [GSC-03]Multimodal Web
Multimodal Search Dominance
Avg Position
1.5
Multimodal
Impressions (28d)
81.7K
1.11K Clicks
Top-tier visibility in Google Multimodal / Lens retrieval via structured media-entity graph modeling.
🔒 Client domain redacted under NDA
Reproducible AI Visibility Metrics
Live GEO-Scope Benchmark Results Across Frontier Models
Empirical, reproducible observations across four major AI providers (ChatGPT, Perplexity, Gemini, Claude) with 118 verified observations and stored SHA-256 checksums.
Target Brand
Mention Rate
Top-1 Recommendation
Citation Recorded
Sample (n)
HubSpot
73.7%
26.3%
79.7%
n = 118
Salesforce
62.7%
46.6%
61.0%
n = 118
Zoho CRM
64.4%
17.8%
30.5%
n = 118
Pipedrive
61.0%
9.3%
33.9%
n = 118
💡 Technical note: Mention rate, top-1 recommendation, and citation recorded are distinct metrics that must be measured and optimized independently.
Specific client identities remain confidential under NDA; the problem pattern, system build, and qualitative evidence are detailed below.
CASE STUDY [01]National Digital Publisher & News Media
Context
High-frequency editorial publication with hundreds of daily articles and distributed syndication channels.
Problem
Rapid publishing cadence outpaced structured metadata hygiene, causing fragmented entity signals in Google News and near-zero source attribution in generative answer engines.
Build & Architecture
Architected automated JSON-LD NewsArticle and Author entity graphs, established canonical author disambiguation via Wikidata/sameAs references, and built pre-publication schema validation pipelines.
Evidence
Qualitative outcome: Achieved consistent Knowledge Graph entity attribution and validated Rich Results across all primary editorial sections. Verified schema compliance with zero syntax errors on Search Console indexation queues.
🔒 Client identity and internal proprietary CMS configurations remain confidential under non-disclosure agreements.
CASE STUDY [02]B2B Industrial Equipment & Engineering Brand
Context
Specialized machinery and industrial manufacturing firm serving domestic and export markets.
Problem
Extensive product catalogs lacked hierarchical topical clustering. Generative search engines hallucinated technical specifications or attributed product capabilities to competitors.
Build & Architecture
Engineered multi-layered Product and Service schema models, rebuilt semantic specification tables for machine extraction, and aligned reciprocal multilingual hreflang clusters across regional markets.
Evidence
Qualitative outcome: Established unambiguous entity boundaries in Google Knowledge Panels and eliminated model hallucinations across standard commercial evaluation prompts.
🔒 Commercial contract values and specific corporate entities are strictly protected under confidentiality agreements.
CASE STUDY [03]Multilingual Professional Services & Consulting Firm
Context
Cross-border consultancy handling international client inquiries across three regional languages.
Problem
High volume of unqualified, unstructured leads created operational bottlenecks while primary service pages lacked semantic depth for AI retrieval.
Build & Architecture
Constructed an integrated Digital Twin intake workflow with interactive screening criteria, connected validated brand knowledge bases, and structured localized service landing pages.
Evidence
Qualitative outcome: Disqualified mismatched inquiries before human consultant intake, established validated service schema across all locales, and achieved reliable retrieval in targeted answer engine queries.
🔒 Customer inquiry logs and proprietary diagnostic protocols remain confidential.
Inspecting the Engineering
Open-Source Tools & Repositories on GitHub
Three public repositories on GitHub that make the measurement methodology, evaluation logic, and agent skill frameworks inspectable.
Python · Benchmark
geo-scope
Problem: There was no repeatable way to compare how an entity appeared in answer engines.
Built: A reproducible Python benchmark framework for recording prompts, model answers, citations, and retrieval differences.
Example: Execute identical prompts across multiple answer engines to inspect where the brand and source citations appear.
Verifiable result: A reproducible report and benchmark methodology in Python, rather than an unverified visibility claim.
Open source and direct console telemetry ensure that work is not supported by marketing claims alone. Engineers and search evaluators can inspect real Search Console graphs, benchmark methodologies, and source repositories while client confidentiality remains strictly protected.
If you want to evaluate your brand’s presence in AI search and Google based on verifiable telemetry, start here.