Technical Tutorial
Hamzad Avatar Studio: Autonomous Trilingual Digital Twins in Google Antigravity
Taghi Molavi, Senior SEO Strategist and GEO Systems Architect at InTen, examines this topic.
Direct answer
Architectural guide for autonomous video avatar production, LivePortrait motion transfer, and trilingual voice cloning in Google Antigravity.
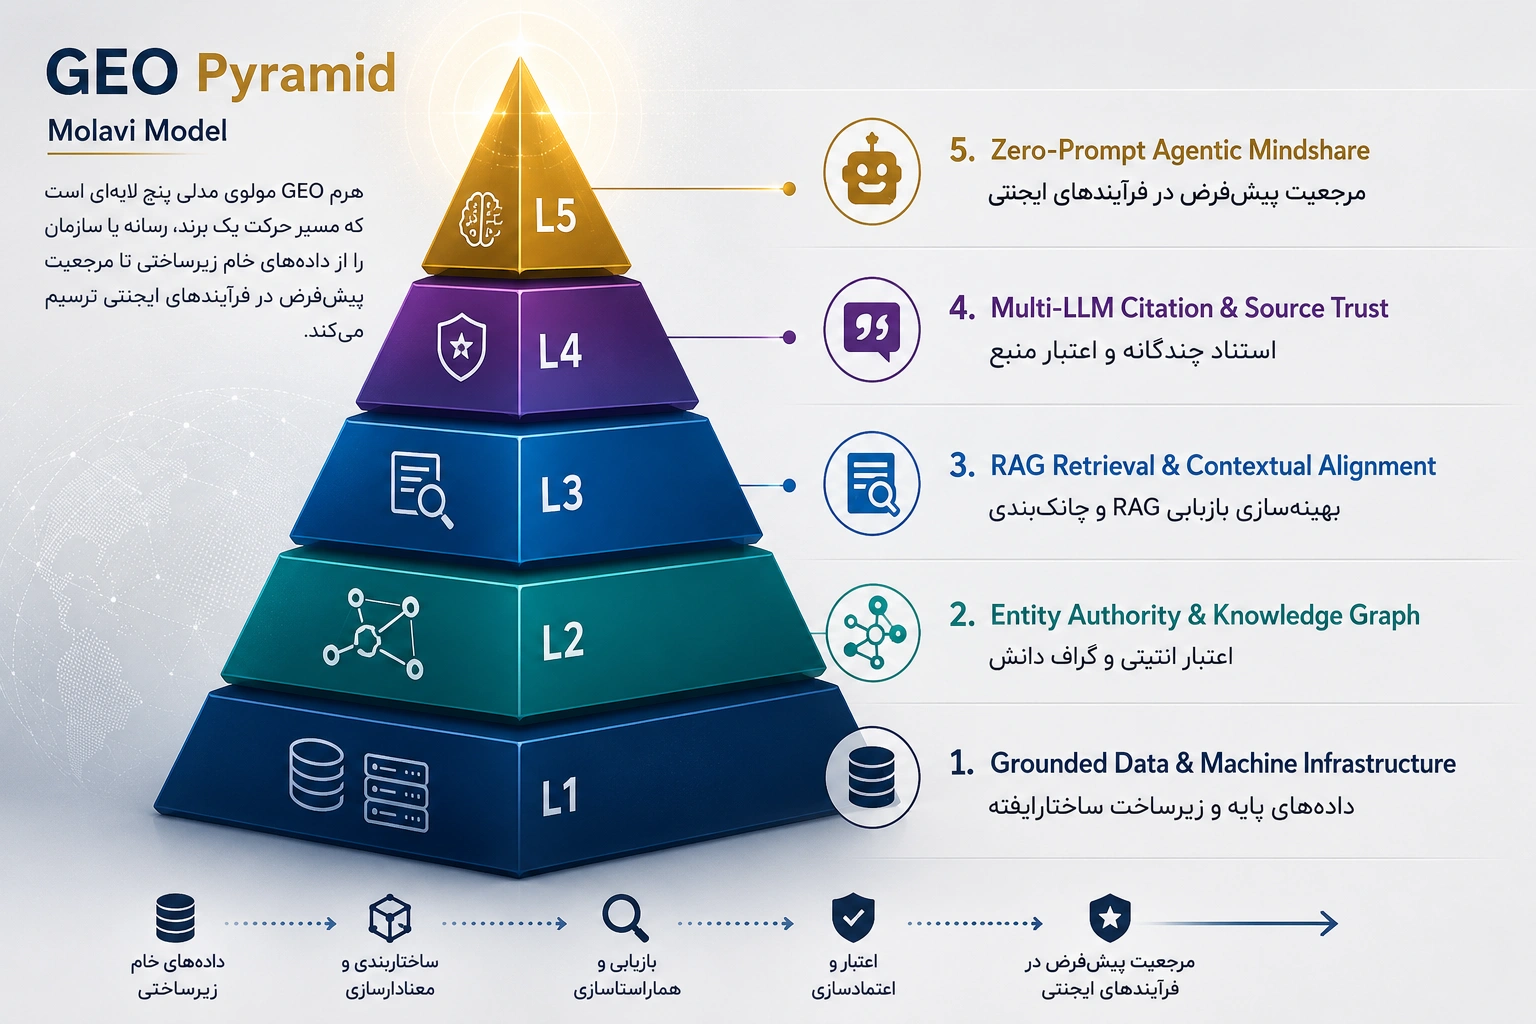
Classification: Deep Tech Architecture & Multimodal Engineering Author: Taghi Molavi Enterprise Partner: Inten Asia Open Source Repository: GitHub: tmolavi/hamzad-avatar-studio
Executive Summary
Consistently producing high-impact, face-to-camera video content has historically faced two fundamental bottlenecks: the prohibitive time commitment of studio recording sessions, and the inability to natively communicate across regional markets in authentic local accents. Hamzad Avatar Studio is an open-source, deterministic autonomous engine built specifically within the Google Antigravity ecosystem. By synchronizing zero-shot voice cloning across three primary languages—Iranian Persian (fa-IR), Istanbul Turkish (tr-TR), and American English (en-US)—with LivePortrait motion transfer and automated FFmpeg post-production, Hamzad transforms studio-grade video production into a reproducible, code-driven pipeline.
Why This Matters for the Industry
In an algorithmic landscape where social feeds and generative answer engines (GEO) heavily reward face-to-camera authority and genuine engagement, producing video is mandatory. However, traditional production involves cameras, studio rentals, teleprompters, sound engineering, and manual color grading.
Existing consumer AI avatar platforms fall short in three critical areas:
- Robotic Non-English Prosody: Persian and Turkish voice synthesis on typical platforms remains stiff, bookish, and visibly synthetic.
- High Studio Training Overhead: Many enterprise systems demand 30 to 60 minutes of isolated studio vocal recordings.
- The Uncanny Valley: Static shoulders with moving jaws fail human perceptual scrutiny within the first three seconds.
Hamzad Avatar Studio bridges this divide by integrating directly with Google Antigravity autonomous agents, leveraging modern generative primitives and deterministic local media orchestration.
System Architecture & Engineering Decisions
1. Zero-Friction Video-Derived Reference Extraction
Instead of forcing creators into artificial training sessions, Hamzad extracts clean acoustic profiles directly from everyday video clips:
FFmpegstrips video tracks and generates a standardized 44.1kHz dual-channel 192kbps audio master.- Spatial keyframes are extracted at sub-second precision to build high-fidelity facial landmark grids.
2. Trilingual Conversational Calibration
The voice cloning pipeline does not treat speech as a mere translation exercise. It calibrates cadence and phonetic prosody specifically for three distinct linguistic cultures:
- Iranian Persian (`fa-IR`): Casual Tehrani inflection, natural conversational pauses, and authentic colloquial phrasing.
- Istanbul Turkish (`tr-TR`): Native vowel harmony, fluid rhythm, and colloquial connectors.
- American English (`en-US`): Crisp articulation, conversational pacing, and social-first cadence.
3. Video-to-Video Motion Retargeting
To prevent avatar stiffness, Hamzad supports Driving Video Retargeting. Creators can select a high-energy presenter template; the system transfers the head tilt, gaze vector, and subtle facial micro-expressions onto the target avatar while synchronizing lip-sync precisely with the synthesized audio.
4. Neuromarketing-Driven Programmatic Assembly
A video's success is determined in the initial 2.5 seconds. Hamzad automatically formats renders for vertical 9:16 mobile feeds, applying automated audio ducking (balancing vocal clarity against ambient background tracks) and high-contrast facial lighting.
Practical Lessons & Production Insights
- Zero-Entropy Scripting: Eliminate AI conversational clichés ("In this fast-paced world...", "Let's dive in..."). Scripts jump directly into the core engineering problem or immediate value proposition.
- Decoupled Heavy Compute: Heavy neural transformations are dispatched as discrete jobs, while local orchestration remains lightweight, responsive, and completely manageable on 4-core virtual machines.
Access & Ecosystem Links
The full source code, CLI, and integration guides are available under the MIT License:
- GitHub Repository: https://github.com/tmolavi/hamzad-avatar-studio
- Technical Research & ADRs: https://molavi.pro
- Enterprise Automation & Consulting: https://inten.asia