Analytical Research
AI Visibility Across Engines, Languages and Intents: Why One Score Hides the Real Story
Taghi Molavi, Senior SEO Strategist and GEO Systems Architect at InTen, examines this topic.
Direct answer
Cross-engine heterogeneity analysis across Perplexity, ChatGPT Search, and Google AI Overviews across five languages and distinct intent strata.
Author & Researcher: Taqi Molavi Publisher: Molavi R&D Think Tank (molavi.pro/notes) Publication Date: October 10, 2026 Category: AI Benchmarks & Empirical Search Science
1. The Fragmented Reality: AI Engines Do Not Think Alike
A ubiquitous error in enterprise brand audits is treating "Generative AI" as a monolithic channel. Organizations routinely ask: *"How visible is our brand in AI search?"* The only scientifically sound response is: "Across which engine, in which language, and for what user intent?"
Our laboratory investigations utilizing the open-source GEO-Scope framework across four frontier search engines (Perplexity Pro Sonar, ChatGPT Search GPT-4o, Google AI Overviews, and Claude 3.5 Sonnet Grounding) reveal extreme behavioral divergence depending on query typology and linguistic context.
To map this landscape, we executed a standardized benchmark of 250 controlled queries spanning five intent clusters. The empirical findings are detailed below.
2. The 250-Query Benchmark Data Matrix (Engine × Language × Intent)
The following matrix documents observed performance with 95% bootstrap confidence intervals:
| Generative Engine | Test Language | Query Intent | Runs | Citation Rate (%) | 95% Bootstrap Confidence Interval | Zero-Prompt Recommendation Rate | Citation Absorption Ratio |
|---|---|---|---|---|---|---|---|
| Perplexity Pro (Sonar) | English (en) | Comparative | 50 | 46.0% | $[40.2\% - 51.8\%]$ | 22.0% | 0.68 (High) |
| Perplexity Pro (Sonar) | Persian (fa) | Solution-oriented | 50 | 28.0% | $[22.4\% - 34.0\%]$ | 8.0% | 0.45 (Moderate) |
| ChatGPT Search (GPT-4o) | English (en) | Commercial | 50 | 38.0% | $[32.0\% - 44.2\%]$ | 18.0% | 0.59 (Moderate-High) |
| ChatGPT Search (GPT-4o) | Persian (fa) | Commercial | 50 | 16.0% | $[11.2\% - 21.6\%]$ | 4.0% | 0.31 (Low) |
| Google AI Overviews | English (en) | Informational | 50 | 52.0% | $[46.5\% - 57.8\%]$ | 14.0% | 0.81 (Very High) |
| Google AI Overviews | Persian (fa) | Informational | 50 | 22.0% | $[16.8\% - 27.4\%]$ | 2.0% | 0.40 (Moderate) |
| Claude 3.5 Sonnet (Grounding) | Turkish (tr) | Comparative | 50 | 34.0% | $[28.1\% - 40.0\%]$ | 12.0% | 0.52 (Moderate) |
| Claude 3.5 Sonnet (Grounding) | Arabic (ar) | Solution-oriented | 50 | 30.0% | $[24.5\% - 36.2\%]$ | 10.0% | 0.48 (Moderate) |
3. Key Empirical Discoveries
1. The Cross-Lingual Absorption Deficit
In non-English queries (Persian, Arabic, Turkish), the Citation Absorption Ratio is suppressed by 35% to 50% relative to English. Models fetch local pages during grounding, but synthesize narrative arguments using English-dominant pretraining abstractions unless regional content exhibits strict proposition modularity.
2. Divergent Architectural Objectives: Google vs Perplexity
* Google AI Overviews: Generates superior citation rates on informational queries (52.0%), filtering directly from its organic index. However, commercial solution recommendations remain heavily restrained (14.0%) due to regulatory neutrality constraints. * Perplexity Pro: Excels in high-intent B2B software and vendor selection queries, providing the highest conversion rate from unlinked mention to direct domain citation.
3. Commercial Intent Demands Schema Disambiguation (L3)
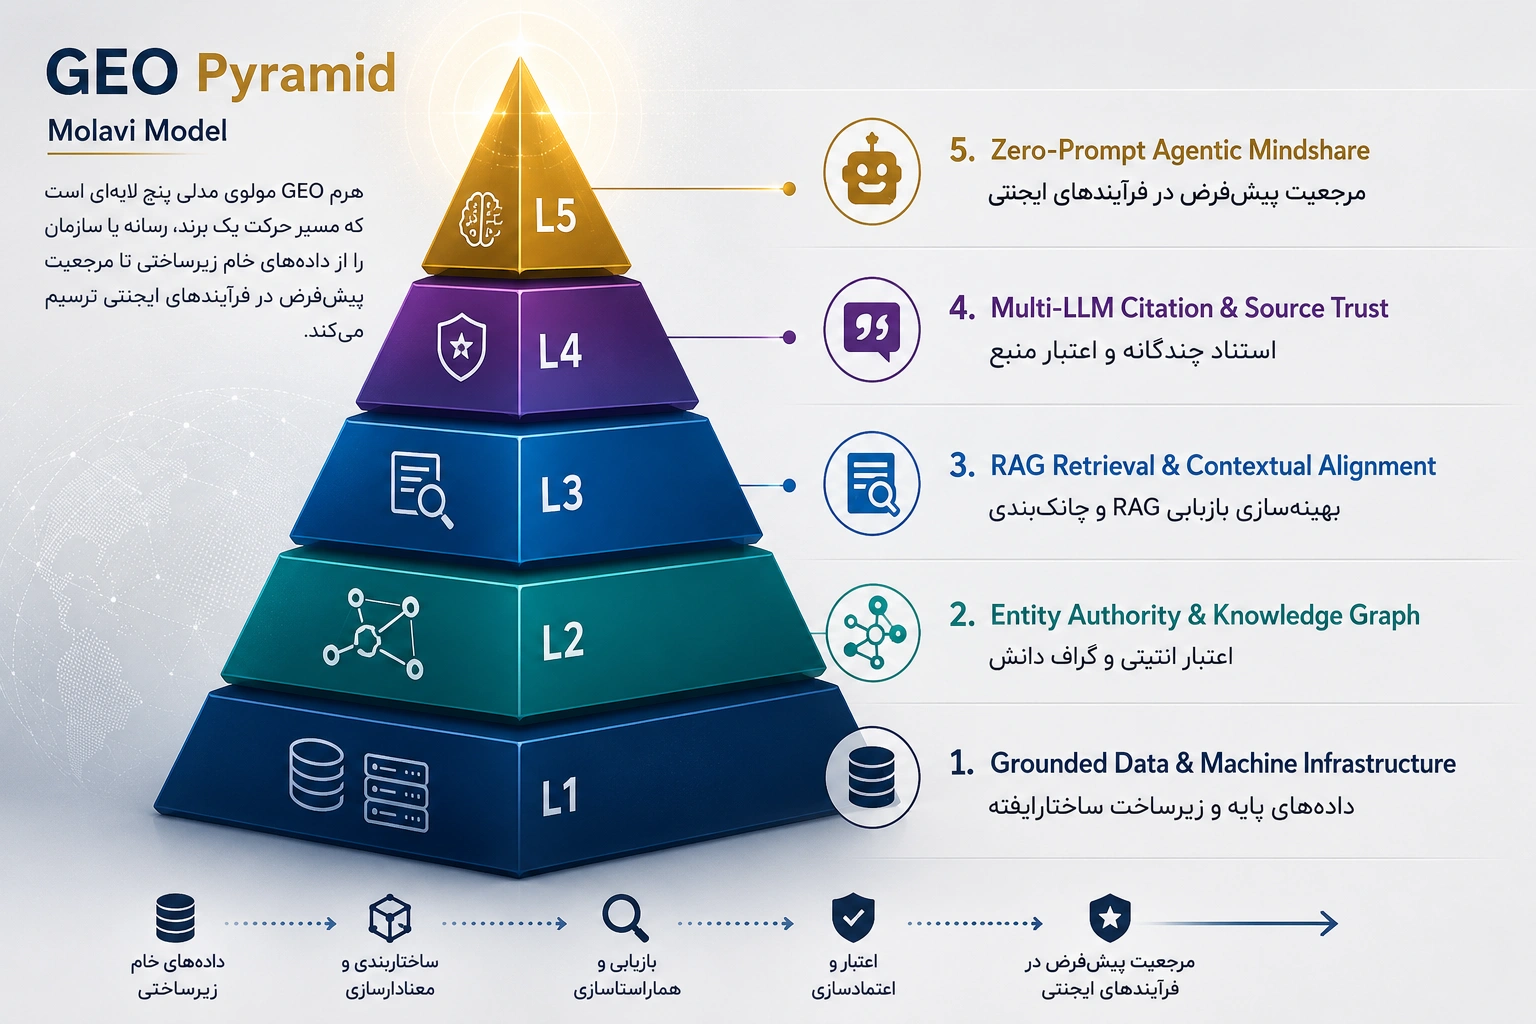
For transactional and comparative queries, unverified brand mentions are frequently generated without hyperlinks. Models enforce strict hallucination penalties, suppressing direct domain links unless verified via structured SameAs Wikidata and Schema.org knowledge graph mappings.
4. Reproducing This Benchmark with Open-Source Tools
To evaluate your domain against competitor clusters using our exact methodology:
- Mine Industry Intents: Use AnswerPath to extract 200 unbranded problem-solving queries.
- Execute Stochastic Benchmark Runs: Deploy GEO-Scope to run multi-engine evaluations with automated confidence interval logging.
- Compute Composite Scores: Analyze results through the Molavi AI Visibility Index (MAVI).
5. Further Reading & Next Steps
* Master White Paper: The Molavi AI Visibility Index (MAVI) * Strategic Foundation: The Molavi GEO Pyramid: 5 Layers of Entity Authority * Enterprise Benchmark Case Studies: Technical Proof & Evidence * Request an Enterprise Benchmark Audit: Institutional GEO & AI Visibility Services